Weighted tokens, explained: pick the right plan and make it last
How apmix meters usage across every model with one allowance, how to turn a plan into real tokens on any model, and practical ways to make a month's allowance go further.
 The apmix teamPublished 4 min read
On this page
Every model has a different price. A token from a fast model costs a fraction of a token from a frontier model, and reasoning modes cost more again. Most gateways handle that with a price list per model and a bill you only understand at the end of the month. apmix uses one unit for everything instead: the weighted token.
One unit across every model
Your plan is a monthly budget of weighted tokens, shared by every model in the plan and every key on your account. Each model has a multiplier: how many weighted tokens one real token costs on that model.
- On a 1× model, a real token costs one weighted token.
- On a 3× model, the same token costs three.
- Prompt and completion tokens are both counted, reasoning tokens included, then multiplied by the model's rate.
So a 1,000-token exchange costs 1,000 weighted tokens on a 1× model and 3,000 on a 3× model. Multipliers are set per model; the pricing page, each model's own page and your dashboard always show the current value.
Turn a plan into real tokens
The useful question is not "how many weighted tokens do I get" but "how much can I actually send to the model I use". The answer is one division:
Real tokens a month = plan allowance ÷ model multiplier
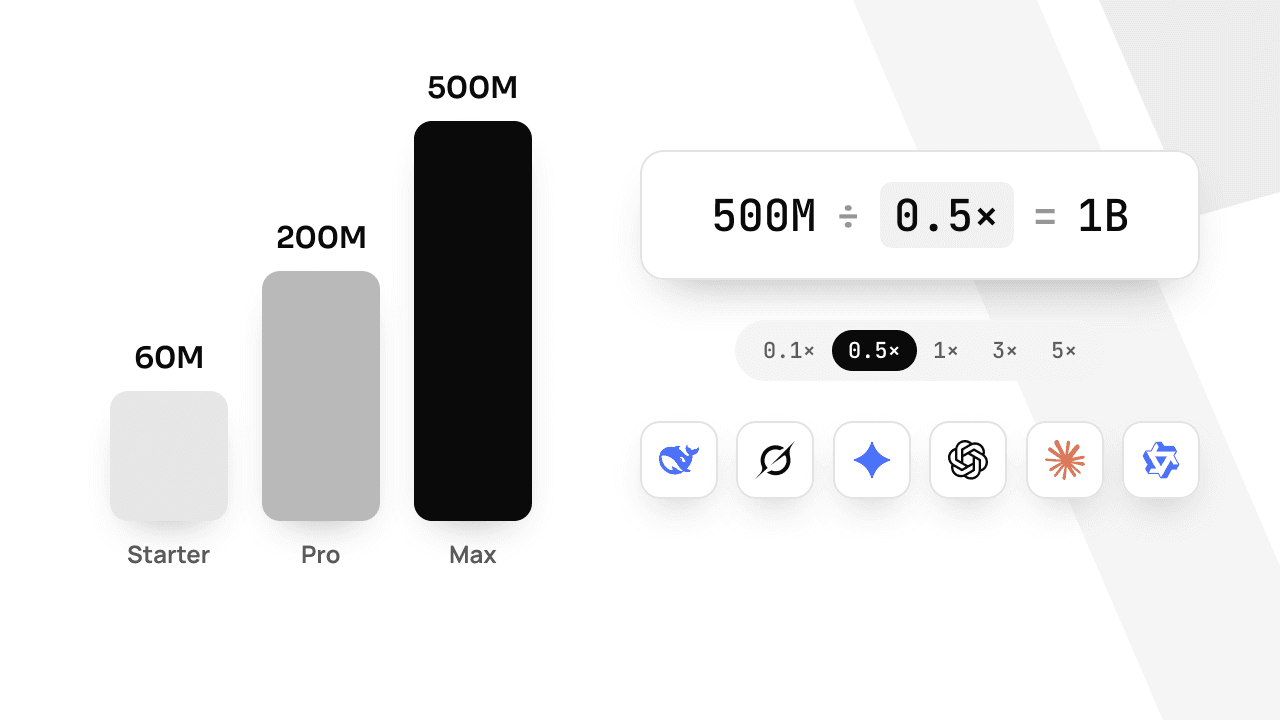
Here is what each plan's monthly allowance buys at a few multipliers:
At the time of writing, some fast models even cost less than 1×: at 0.5×, Starter's 60M buys 120M real tokens, and at 0.1× it buys 600M.
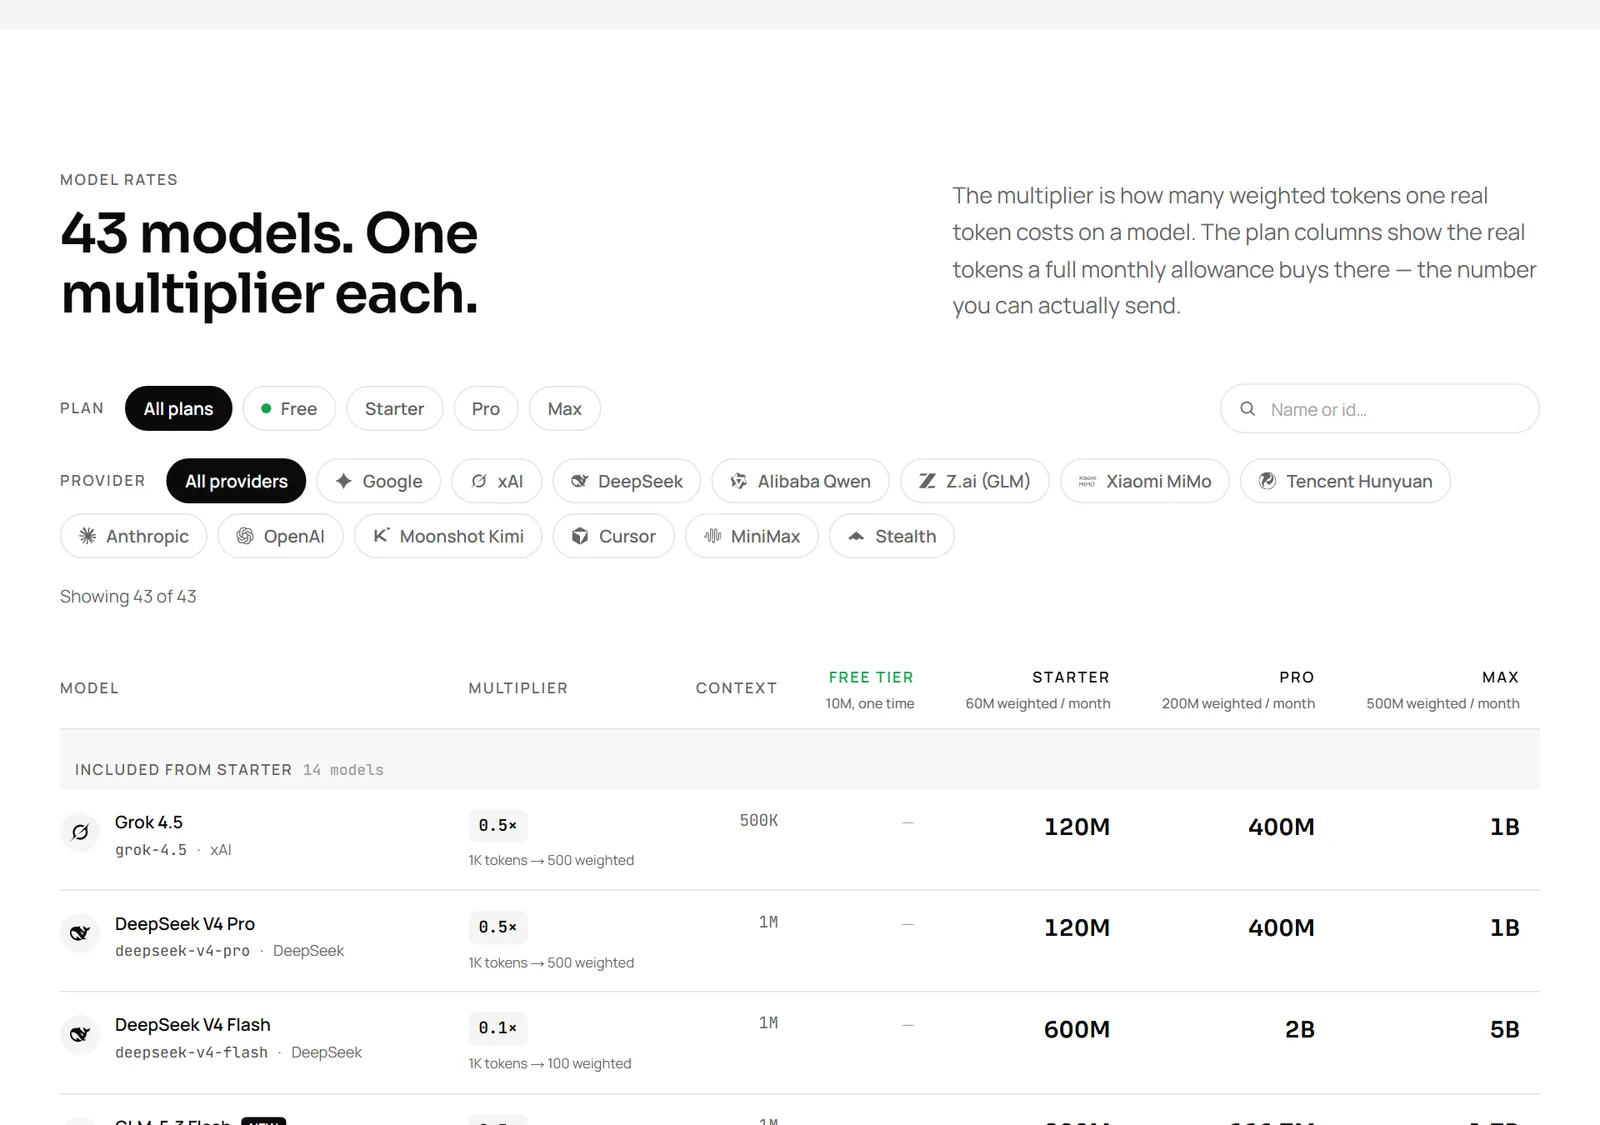
The pricing page does this for every model in the catalog, so you can check the exact figure for the models you use before choosing a plan.
Which plan fits you?
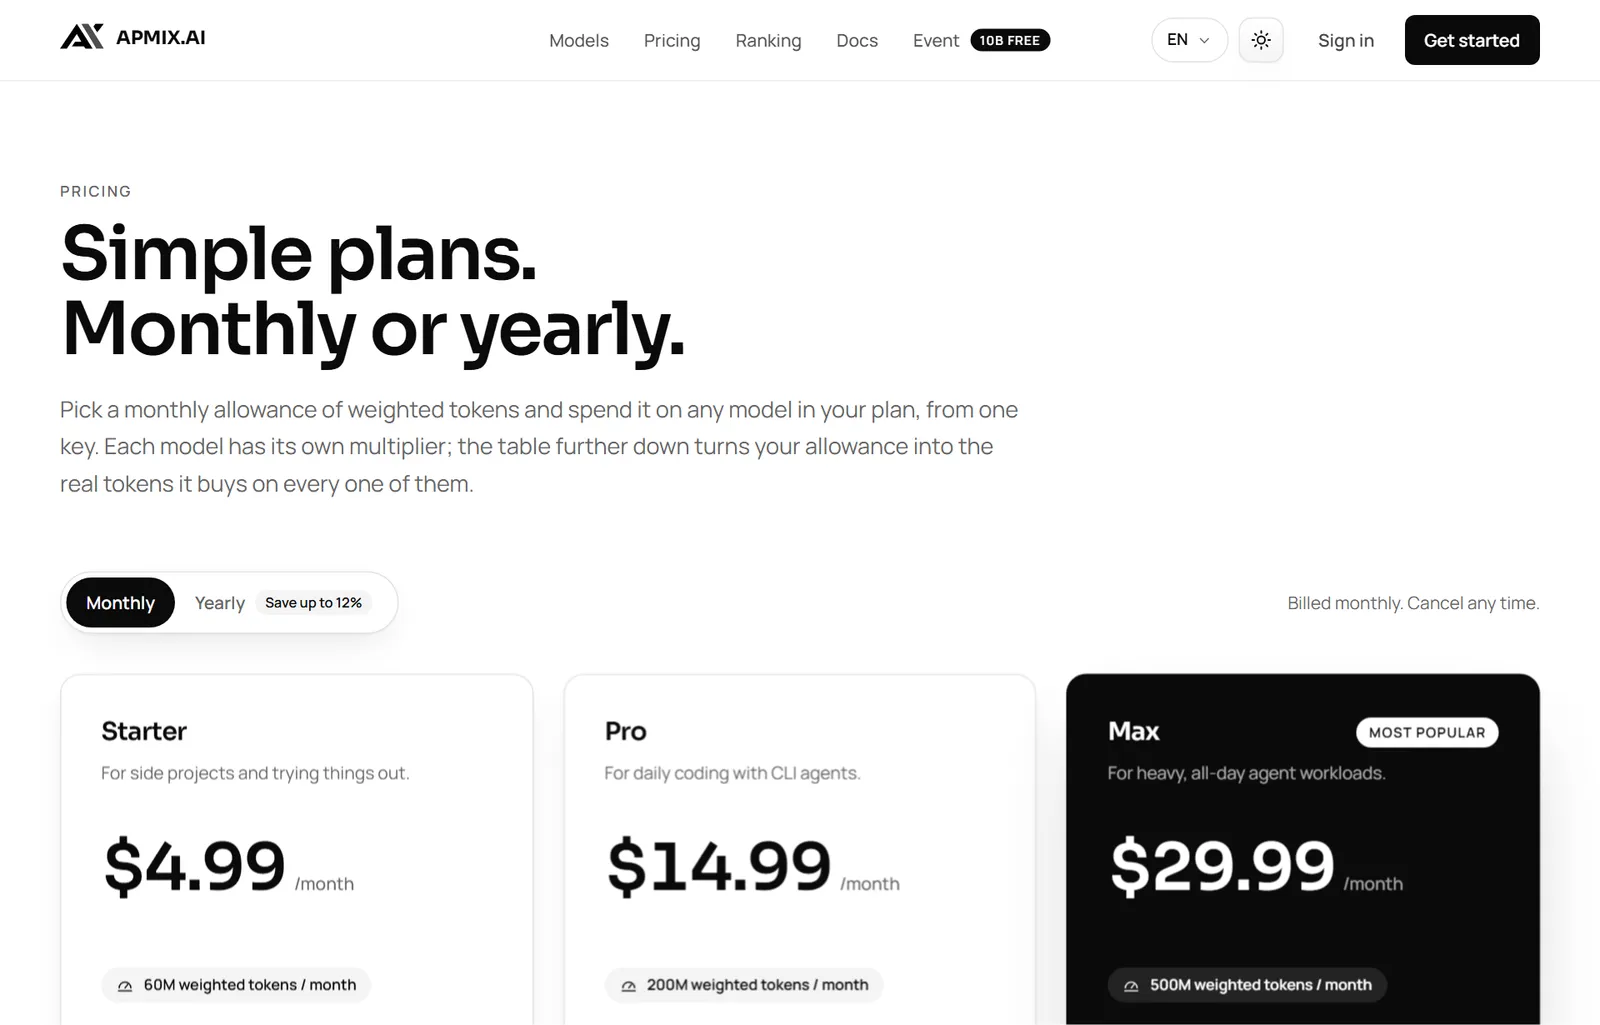
- Starter ($4.99/month, 60M) fits side projects, evaluations and occasional agent sessions, mostly on fast models.
- Pro ($14.99/month, 200M) is built for daily coding with CLI agents like Claude Code or Codex, and adds more models.
- Max ($29.99/month, 500M) is for heavy, all-day agent workloads. It covers the whole catalog, allows unlimited keys and gets priority routing.
Plans are tiered: a higher plan includes every model of the plans below it. Yearly billing gives the same monthly allowance for twelve months at a lower price, paid once.
Make the allowance last
A few habits make a real difference, especially with agents that send long contexts:
- Match the model to the job. Use a fast, low-multiplier model for routine edits, tests and small refactors, and switch to a frontier model for the hard parts. The same allowance goes three to five times further on a 1× model than on a 3× or 5× one.
- Use reasoning modes on purpose. They count at higher rates. Turn them on for architecture and tricky bugs, not for renaming variables.
- Keep agent sessions focused. Every turn resends the conversation. Starting a fresh session for a new task is cheaper than dragging a huge context along.
- Watch the live logs. Dashboard → Logs shows every request with its model, tokens and weighted cost as it happens.
- Set your own limits. Optional daily and weekly caps in Settings stop a runaway loop, and email alerts at 50, 70, 80 or 90% tell you where you stand.
Developers can read the meter from code too. Every response carries x-apmix-weighted-tokens, what that request cost, and x-apmix-remaining, what is left of the month.
When a month runs short
If you use up the allowance, requests return a clear allowance_exhausted error until the monthly reset. You have two ways to keep going right away:
- Upgrade. It applies immediately and the difference is charged pro rata.
- Buy a top-up. One-time packs of 10M, 30M, 60M or 100M weighted tokens, from $1.49 on Max, $1.79 on Pro and $1.99 on Starter for 10M. Top-ups are spent after the monthly allowance and never expire while you have a plan.
Fair billing
Monthly plans are refundable in full while less than 5% of that month's allowance has been used, and unused top-ups are refundable for 14 days. Yearly plans are not refundable. The refund policy has the exact numbers for every plan.
Still deciding? New accounts get free tokens on the free models, no card needed, so you can see your own usage in weighted tokens before you pick a plan. Create an account and look at the meter after your first session.